You signed in with another tab or window. Reload to refresh your session.You signed out in another tab or window. Reload to refresh your session.You switched accounts on another tab or window. Reload to refresh your session.Dismiss alert
{{ message }}
Repository navigation
fix(server): an effect this build can't read no longer blocks its thread's later work - #32746
EffectOutbox.claimNext marks an outbox row running under the worker's lease, then decodes its payload_json. If this build cannot decode the payload, the claim fails and the row stays running. claimableCandidatePredicate then holds back later effects in the same thread's effect lane: turn starts, interrupts, checkpoints and delegated stops. nextClaimableAt reports no work for it. reconcileAfterProcessLoss only touches effect types this build knows, so restarting the same build does not clear an unknown effect type. The thread looks dead with no error in the UI. The worker logs one failed claim and the row stays running under its lease; recovery needs database repair or a build that understands and reconciles that effect type.
A same-build round trip is safe, because encode and decode share one schema.
Change
claimNext now decodes the claimed row before it registers the cancellation signal. If decoding fails, it logs a warning with the effect id and type. Then it settles the row through the existing fail path: failed, lease cleared, last_error "This server build cannot decode the <type> effect.", settled waiters signalled and claimers woken. Then it claims again in the same call, so the thread's next effect runs and drain and recovery don't stop early.
failed (not cancelled) keeps the row as evidence. There is no new status, contract change or migration. EffectOutboxErrors from fail pass through unwrapped, as listByCommandId and nextClaimableAt already do.
Scope and approval
This is a small, focused fix for an obvious bug: one function in EffectOutbox.ts plus one test. It changes no product behavior. A row that could never run now fails visibly instead of holding its thread forever. It does not touch the claim SQL or claimableCandidatePredicate, so it does not overlap #30669 (open) or #26272 (now on main), and it merges cleanly with current main. Recovering rows that an older build already left running is a separate change and is not part of this PR.
Prior PRs: none. This change does not reuse an earlier patch; #30669 and #26272 are separate changes checked for overlap.
Verification
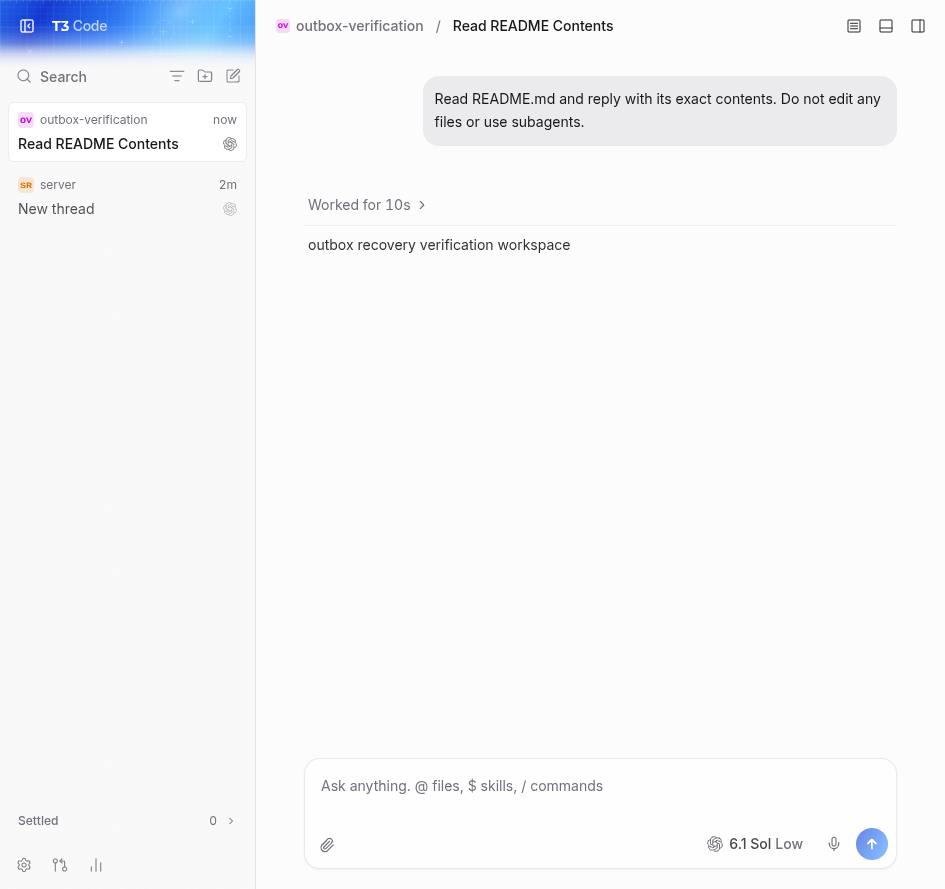
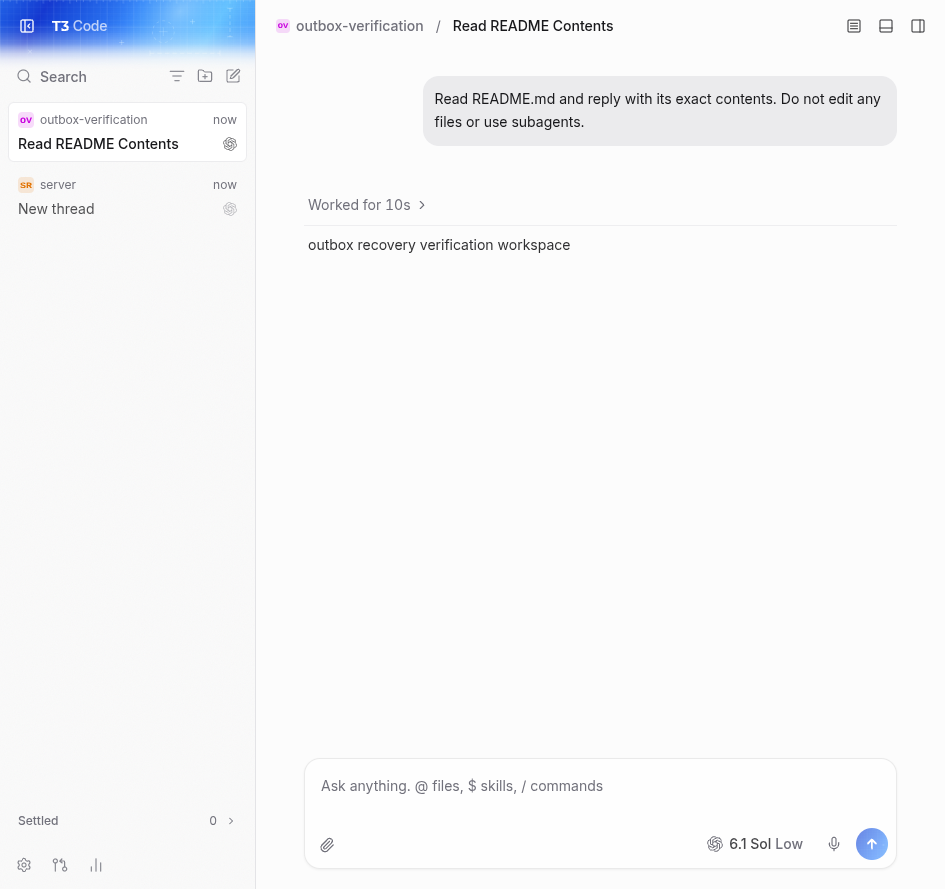
I made the row by real use on today's main (cd8fc91a57), which knows the newer type provider-session.apply-model-selection (#34563), and opened two copies of that T3 home with builds that don't. Input went through the web app in T3's Browser panel. Claude Haiku 5.5 was signed in by a fresh claude auth login (subscription) in an isolated config dir.
On main, mid-turn, I paused the Claude CLI (SIGSTOP), pressed Stop and changed effort while the interrupt waited, then killed the server. That left the interrupt running and the provider-session.apply-model-selection effect pending. On each copy I sent "Reply with the single word: ready." in that thread.
Before, a02bc75737 (the parent of #34563, without this fix): one failed claim at startup, and 95 seconds after the send the turn had not started.
After, this PR's head 05893b779e: the row fails, then the recovery and the new turn run.
After, 05893b779e, the server log lines naming the failure, then the rows:
[00:50:34.519] WARN (#1050): Failing an orchestration effect this build cannot decode
    effectType: 'provider-session.apply-model-selection',
rowid|effect_type|status|last_error
9|provider-turn.interrupt|cancelled|Cancelled because the server restarted before the provider work completed.
10|provider-session.apply-model-selection|failed|This server build cannot decode the provider-session.apply-model-selection effect.
11|provider-runtime.continue|succeeded|
12|provider-turn.start|succeeded|
run|status
4|cancelled
5|completed
6|completed
The merge with today's main (4e3498f643, clean) knows the type and runs the effect, so it can't show this; there the new test fails with main's EffectOutbox.ts and passes with this PR's (whole file: 61 passed).
Not checked: released builds (both ran from source), and a crash between the claim and the fail update.
Generated with Claude Opus 5.5 and GPT-6.1 Sol in T3 Code Nightly
…ead's later work

claimNext marked an outbox row running under the worker's lease before
decoding its payload. A payload this build could not decode (an effect type
from a newer build after a downgrade, or a damaged row) failed the claim and
left the row running, so every later effect on that thread stayed blocked,
including across restarts.

claimNext now decodes before registering the cancellation signal. On a decode
failure it logs a warning, settles the row as failed with a last_error through
the existing fail path, and claims again so the thread's next effect runs.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
Macroscope's review found this PR approvable — Unreadable effects now fail with a recorded reason rather than blocking later work on their thread. Normal claim ordering remains unchanged, and failed payloads are retained for investigation.
You can add or adjust custom eligibility rules. Learn more.
No actionable comments were generated in the recent review.
Walkthrough
EffectOutboxV2.claimNext now fails a claimed effect when its payload cannot be decoded, then continues searching for a decodable effect. A persistence test checks the failure state, lease cleanup, recorded error, and claim of the next effect.
Changes: Outbox decode failure handling
Layer / File(s)
Summary
Claim and fail undecodable effects apps/server/src/orchestration-v2/EffectOutbox.ts, apps/server/src/orchestration-v2/FoundationPersistence.test.ts
claimNext logs and fails an undecodable claimed effect, then tries another claim. The test verifies that the failed row has no lease owner and that the next valid effect is claimed.
pingdotgg/t3code#31466: Adds an outbox effect type that older builds cannot decode. This PR handles undecodable pending rows.
Suggested reviewers:t3dotgg, macroscopeapp
Merge Risk: Minimal · up to 05893
The change allows later effects on a thread to proceed when this server cannot decode an earlier effect. No actionable merge-blocking risk remains after normal checks.
Pre-merge checks: 4
Check name
Status
Explanation
Title check
The title names the primary change: an effect this server build cannot decode no longer blocks later work on its thread. It matches the EffectOutbox.claimNext change, which settles the undecodable row…
Linked Issues check
Check skipped because no linked issues were found for this pull request.
Out of Scope Changes check
Check skipped because no linked issues were found for this pull request.
Description check
The description follows the repository template closely. It covers the Problem, Change, Scope and approval, and Verification sections, and it gives concrete reproduction steps, before/after evidence, …
Full details: Title check
Explanation
The title names the primary change: an effect this server build cannot decode no longer blocks later work on its thread. It matches the EffectOutbox.claimNext change, which settles the undecodable row as failed and claims again in the same call. The title follows conventional commit form with the fix(server) scope. It is specific and clear, and it does not use vague terms.
Full details: Description check
Explanation
The description follows the repository template closely. It covers the Problem, Change, Scope and approval, and Verification sections, and it gives concrete reproduction steps, before/after evidence, and the commands and results observed. The Scope and approval section explains why the change qualifies as a small, focused bug fix without a prior issue. It states that no prior issue or maintainer discussion is linked. The Scope section says "Prior PRs: none" but then cites #30669 and #26272 as separate changes, which is slightly contradictory wording. The Verification section states what was not checked. The template's opening comment asks for a conventional commit title, and the PR body does not show one. The title is outside the provided description text, so this check cannot confirm it. The author also names the agents used in the final line, which the template requests. Overall the description is mostly complete.
Finishing Touches
Generate unit tests (beta)
Create a new PR
Autofix · Keep fixing CodeRabbit findings and required CI, and resolving merge conflicts
only neighboring behavior is verified; the unreadable-effect recovery is not verified in the running app.
checked exact head 05893b779edf4d443e709d6e1168f044edbf42ae after running github/main (4c361199f47f6ea32a2c14835df392640d0f7c63) in a separate worktree. installed dependencies in both. ran one background dev server at a time. drove the web client with the repo's playwright and /usr/bin/google-chrome, added a project pointing at a real git repo, and used real codex gpt-6.1-sol turns through the local provider proxy. final pr verification used an explicit isolated --home-dir /home/user/t3code/.t3.
main: read README through codex; turn-start, title and checkpoint effects succeeded.
pr: read the same README, completed a same-thread follow-up, interrupted a real sleep 60 with stop generation, and completed two subsequent turns on that thread.
read-only database inspection: pr has four completed runs and one interrupted run; five turn-start effects, five checkpoints, one interrupt and one title effect all succeeded.
existing focused persistence test passed through blacksmith-check: one passed, 57 filtered out. that test inserts synthetic rows and is separate from the app evidence.
main, normal codex turn:
pr, matching normal codex turn:
pr, real provider interruption (playback and seeking checked):
the original unreadable-row bug was not reproduced on main, and the new failure-and-continue branch was not reached in the running app. these exact builds have identical effect request schemas, and enqueue encodes with the same schema claimNext decodes. switching between them cannot generate an incompatible row. producing the trigger would require external corruption, an incompatible writer, or database fault injection; the task prohibits fabricated fixtures. no database rows were inserted or damaged for this verification.
recovery of already-running unreadable rows is outside this pr's stated scope. no native desktop, ios/android, other providers, or actual downgrade from an incompatible build was exercised. no code changes were made. this is partial runtime evidence, not verification of the fix itself.
Thank you, @maria-rcks, for running this head next to main with real Codex turns. Your run shows the change leaves normal work alone. On this branch one thread took a follow-up, a stopped sleep 60 and two more turns, and every turn-start, checkpoint, interrupt and title effect on it succeeded.
You're right that switching between main and this PR can't reach the new branch. Both builds use the same schema to encode and decode, so neither writes a row the other can't read. The rows this fixes are ones an older build can't decode: an effect type a newer build added, or a damaged payload_json. That's why the focused test and the transcript in the description write such a row directly.
The gaps you listed stay open: the failure-and-continue branch in a running app, a real downgrade between two builds, other providers and native clients. Recovering rows an older build already left running stays out of scope, as you noted.
Thanks, @maria-rcks, for naming exactly what your run could not reach.
A new run covers two of your items, the failure-and-continue branch in a running app and a real downgrade: I left a newer effect type pending by real use on main, then opened copies of that T3 home with a02bc75737 (without this fix) and with this PR's head 05893b779e. On a02bc75737 the claim failed at startup and the thread stayed at "Working" with no reply; on 05893b779e the row was marked failed, the thread's next effects ran and Claude replied "ready" (Verification).
This branch has not been deployed
No deployments
This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
size:S10-29 changed lines (additions + deletions).vouch:unvouchedPR author is not yet trusted in the VOUCHED list.
2 participants
Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.


 github-actions
Bot
added
vouch:unvouched







Problem
EffectOutbox.claimNextmarks an outbox rowrunningunder the worker's lease, then decodes itspayload_json. If this build cannot decode the payload, the claim fails and the row staysrunning.claimableCandidatePredicatethen holds back later effects in the same thread's effect lane: turn starts, interrupts, checkpoints and delegated stops.nextClaimableAtreports no work for it.reconcileAfterProcessLossonly touches effect types this build knows, so restarting the same build does not clear an unknown effect type. The thread looks dead with no error in the UI. The worker logs one failed claim and the row staysrunningunder its lease; recovery needs database repair or a build that understands and reconciles that effect type.How a row this build can't read gets there:
Migrations.tslogs "Database migration history diverges from this build" and starts anyway. The effect request union has grown since:delegated-tasks.stop(fix(server): Stop also stops delegated tasks and pull request watches #16002),preview.cleanup(fix(server): environment-hosted browser tabs behave like a normal browser #16963) andscheduled-tasks.cleanup(fix(server): delete thread-bound automations with their thread #22070) are all newer variants. A thread with one of those still pending or running when you roll back a nightly, or open the same T3 home from an older desktop build, is stuck on the older build.payload_json.A same-build round trip is safe, because encode and decode share one schema.
Change
claimNextnow decodes the claimed row before it registers the cancellation signal. If decoding fails, it logs a warning with the effect id and type. Then it settles the row through the existingfailpath:failed, lease cleared,last_error"This server build cannot decode the<type>effect.", settled waiters signalled and claimers woken. Then it claims again in the same call, so the thread's next effect runs anddrainand recovery don't stop early.failed(notcancelled) keeps the row as evidence. There is no new status, contract change or migration.EffectOutboxErrors fromfailpass through unwrapped, aslistByCommandIdandnextClaimableAtalready do.Scope and approval
This is a small, focused fix for an obvious bug: one function in
EffectOutbox.tsplus one test. It changes no product behavior. A row that could never run now fails visibly instead of holding its thread forever. It does not touch the claim SQL orclaimableCandidatePredicate, so it does not overlap #30669 (open) or #26272 (now on main), and it merges cleanly with current main. Recovering rows that an older build already leftrunningis a separate change and is not part of this PR.Prior PRs: none. This change does not reuse an earlier patch; #30669 and #26272 are separate changes checked for overlap.
Verification
I made the row by real use on today's main (
cd8fc91a57), which knows the newer typeprovider-session.apply-model-selection(#34563), and opened two copies of that T3 home with builds that don't. Input went through the web app in T3's Browser panel. Claude Haiku 5.5 was signed in by a freshclaude auth login(subscription) in an isolated config dir.On main, mid-turn, I paused the Claude CLI (
SIGSTOP), pressed Stop and changed effort while the interrupt waited, then killed the server. That left the interruptrunningand theprovider-session.apply-model-selectioneffectpending. On each copy I sent "Reply with the single word: ready." in that thread.Before,
a02bc75737(the parent of #34563, without this fix): one failed claim at startup, and 95 seconds after the send the turn had not started.After, this PR's head
05893b779e: the row fails, then the recovery and the new turn run.Outbox rows (read-only) and server log lines
Main, rows after the kill:
Before,
a02bc75737, the server log lines naming the failure:After,
05893b779e, the server log lines naming the failure, then the rows:The merge with today's main (
4e3498f643, clean) knows the type and runs the effect, so it can't show this; there the new test fails with main'sEffectOutbox.tsand passes with this PR's (whole file: 61 passed).Not checked: released builds (both ran from source), and a crash between the claim and the
failupdate.Generated with Claude Opus 5.5 and GPT-6.1 Sol in T3 Code Nightly